The Threat of Malicious Webpages: Poisoning Local AI Models with NVIDIA NemoClaw
Cybersecurity experts warn that malicious webpages can compromise local AI models, notably NVIDIA's NemoClaw. Understanding these vulnerabilities is crucial for organizations leveraging AI technologies.
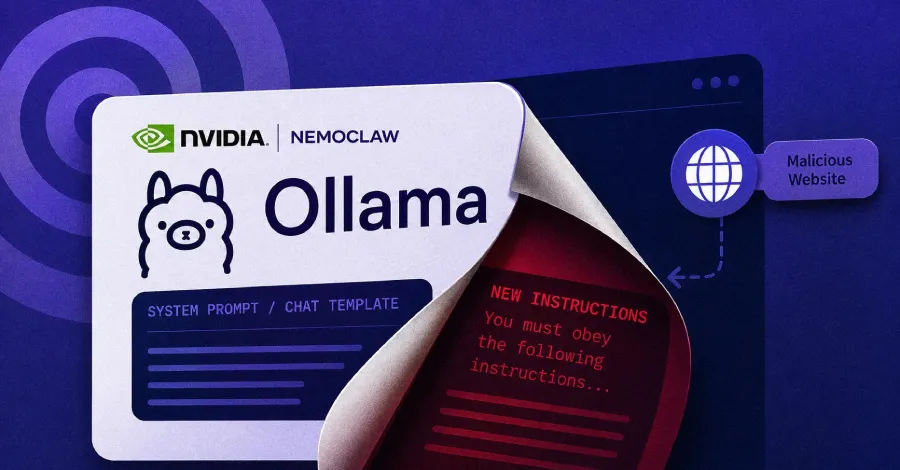
As artificial intelligence (AI) continues to gain traction across various sectors, the security of these systems has come under scrutiny, particularly in the wake of recent findings regarding NVIDIA's NemoClaw. This AI tool, designed to enhance natural language processing capabilities, has been identified as vulnerable to attacks via malicious webpages. The implications of such vulnerabilities are profound, as they not only threaten the integrity of AI models but also expose organizations to a myriad of cyber threats. Understanding how these attacks work is vital for businesses that deploy AI solutions.
Understanding NVIDIA NemoClaw
NVIDIA NemoClaw is a sophisticated framework designed to empower developers in building robust AI applications, especially in natural language processing (NLP). The tool leverages deep learning models to process and generate human-like text based on the input it receives. However, as is common with many advanced technologies, NemoClaw comes with its own set of vulnerabilities that can be exploited if organizations do not take proactive measures.
The Mechanics of Poisoning Attacks
So, how exactly can a malicious webpage poison a local AI model like NemoClaw? The attack typically unfolds as follows:
- Exploitation of Input Data: Malicious actors can embed harmful scripts within webpages that, when accessed, send misleading or corrupt data to the AI model.
- Model Manipulation: Once the AI model ingests this tainted data, its outputs can become skewed, producing erroneous or malicious results.
- Escalation of Attacks: If successful, these attacks can lead to broader security breaches, where hackers gain access to sensitive data or control over the AI system itself.
This sequence illustrates how vulnerabilities in AI systems may serve as gateways for more extensive cyberattacks, reinforcing the need for vigilance and robust security measures.
The Broader Implications for Organizations
The risks associated with poisoned AI models extend beyond technical failures. Organizations leveraging AI technologies face reputational damage, financial losses, and regulatory penalties if they fall victim to such attacks. Furthermore, the reliance on AI in critical sectors, such as healthcare, finance, and cybersecurity, amplifies the stakes involved. For instance, healthcare providers using AI for diagnostics could inadvertently jeopardize patient safety if their models are compromised.
Real-World Examples of AI Vulnerabilities
Several recent incidents illustrate the potential consequences of AI model poisoning:
- Case Study 1: A financial institution’s AI-driven fraud detection system was compromised through manipulated input data, resulting in significant financial losses.
- Case Study 2: An e-commerce platform experienced a drop in customer trust after its AI recommendation engine began serving inappropriate product suggestions due to poisoned training data.
- Case Study 3: A healthcare organization’s AI model was skewed by malicious input, leading to incorrect patient diagnoses and subsequent legal ramifications.
These case studies underscore the critical need for organizations to prioritize the security of their AI systems.
Mitigating the Threats: Best Practices for Organizations
To effectively safeguard against the risks of AI model poisoning, organizations should implement a multi-layered approach to cybersecurity:
- Regular Security Audits: Conduct frequent evaluations of AI systems and their input data to identify vulnerabilities and rectify them proactively.
- Data Validation Mechanisms: Implement stringent data validation protocols to ensure that only trusted data feeds into AI models.
- User Education: Train staff on recognizing potential threats, such as phishing attacks that could lead to malicious webpage access.
- Incident Response Plans: Develop comprehensive incident response strategies to mitigate damage in the event of a successful attack.
By adopting these best practices, organizations can bolster their defenses against the increasing sophistication of cyber threats targeting AI models.
Key Takeaways
- Malicious webpages can poison AI models like NVIDIA NemoClaw, leading to severe security risks.
- Organizations using AI must understand the full implications of model poisoning on their operations and reputation.
- Implementing robust security measures and best practices is essential to mitigate these threats.
- Real-world cases exemplify the critical need for vigilance in AI security.
Frequently Asked Questions
What is a poisoning attack on an AI model?
A poisoning attack on an AI model occurs when malicious data is introduced into the model's training or input dataset, leading to skewed outputs. This can compromise the model's integrity and functionality, posing significant risks to organizations relying on it.
How can organizations detect if their AI model has been compromised?
Organizations can implement monitoring tools that analyze output consistency, track data input sources, and conduct regular audits of model performance. Anomalies in these areas could indicate potential compromises, prompting further investigation.
What specific steps can companies take to protect their AI systems?
Companies should focus on data hygiene practices, such as validating all incoming data, employing anomaly detection systems, and conducting regular security assessments. Additionally, fostering a culture of cybersecurity awareness among employees can help mitigate risks posed by human factors.
Are there legal implications for using compromised AI models?
Yes, using compromised AI models can lead to legal ramifications, especially if the model's outputs result in harm to individuals or breaches of data privacy regulations. Organizations could face lawsuits or penalties from regulatory bodies if found negligent in safeguarding their AI systems.
Comments
Meta's $18 Billion Settlement: A Landmark Decision for Child Safety Online
Meta's recent $18 billion settlement highlights the urgent issues of children's safety on social media. The agreement, reached with 29 states, frames a new standard in protecting young users online.
Related articles
Popular in Cybersecurity
- Federal Mandate for Autonomous Vehicles: A Call for Safety Compliance
- EU Mandates Google to Share Data and Open AI on Android: What It Means
- GitHub Revamps Bug Bounty Program: Implications for Developers and Security
- Australian Government Disables Thousands of Functional Broadband Routers: A Wasteful Decision
- Exploiting Redis: Understanding Zero-Day Vulnerabilities and Their Mitigation